Databricks Feature Store overview and glossary
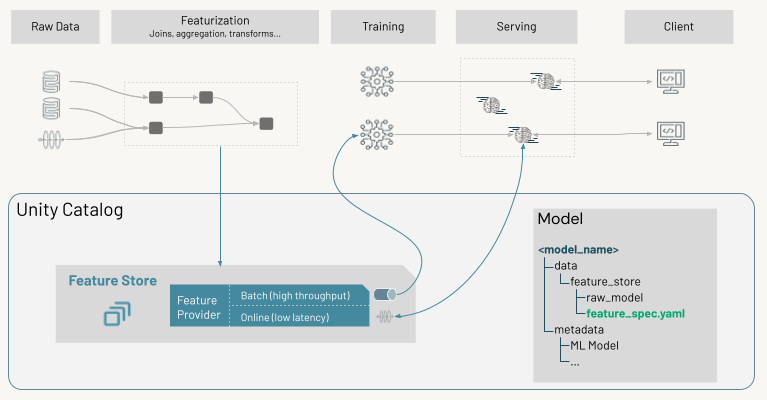
Databricks Feature Store centralizes the features used in machine learning so the same feature computations run during model training and inference. You author features as Feature Views, which Databricks computes and manages, or as feature tables that you populate yourself. The sections below cover the typical workflow and define key terms.
What does Databricks Feature Store offer?
Feature Store gives you two ways to author features. Both produce Unity Catalog-governed features that you can use for batch inference, or else publish to the Online Feature Store for low-latency serving:
- Feature Views define features declaratively, and Databricks computes and manages the feature pipelines for you. Databricks recommends Feature Views for new use cases.
- Feature tables are Delta tables that you populate yourself by writing feature values.
For how to choose between them, see Choose an authoring strategy.
How does Databricks Feature Store work?
The typical machine learning workflow using feature engineering on Databricks follows this path:
- Prototype Feature Views in a notebook, using the Feature Engineering SDK to generate historical data and training sets. Iterate on your feature definitions, your data, and your model in parallel until you are satisfied.
- Productionize:
- Register your features to Unity Catalog, making them governable and reusable assets.
- Train and log your model in MLflow, capturing lineage to the features used in training.
- Materialize your features to online or offline stores.
- Inference:
- For batch, use
score_batch. - For online, set up an online serving endpoint for models or features.
- For batch, use
Feature Store glossary
Feature store
A feature store is a centralized repository that enables data scientists to find and share features. Using a feature store also helps ensure that the code used to compute feature values is the same during model training and when the model is used for inference. You can author features as Feature Views, which Databricks computes and manages for you, or as feature tables. In workspaces enabled for Unity Catalog, any Delta table in Unity Catalog that includes a primary key constraint can be used as a feature table.
Machine learning uses existing data to build a model to predict future outcomes. In almost all cases, the raw data requires preprocessing and transformation before it can be used to build a model. This process is called feature engineering, and the outputs of this process are called features, the building blocks of the model. With Feature Views, you do feature engineering with simple Python definitions, and Databricks manages the pipelines for you.
Developing features is complex and time-consuming. An additional complication is that for machine learning, feature calculations need to be done for model training, and then again when the model is used to make predictions. These implementations might not be done by the same team or using the same code environment, which can lead to delays and errors. Also, different teams in an organization will often have similar feature needs but might not be aware of work that other teams have done. A feature store is designed to address these problems.
Feature Views
Feature Views are an abstraction for defining what a feature is. You define a Feature View, and Databricks computes it. At training time, the Feature Engineering SDK generates point-in-time correct historical feature data and training sets. For inference, materialize the feature to the appropriate online or offline store, and Databricks orchestrates compute ensuring that feature data is ready for serving.
Feature Views support both batch and streaming features, with freshness ranging from sub-second to a scheduled cron.
Feature tables
Feature tables are Delta tables with a primary key. You can sync feature tables to an online store with publish_table. Feature table metadata tracks the data sources from which a table was generated and the notebooks and jobs that created or wrote to the table.
With Databricks Runtime 13.3 LTS and above, if your workspace is enabled for Unity Catalog, you can use any Delta table in Unity Catalog with a primary key as a feature table. See Feature tables in Unity Catalog.
Features in a feature table are typically computed and updated using a common computation function.
You can publish a feature table to an online store for real-time model inference.
FeatureLookup
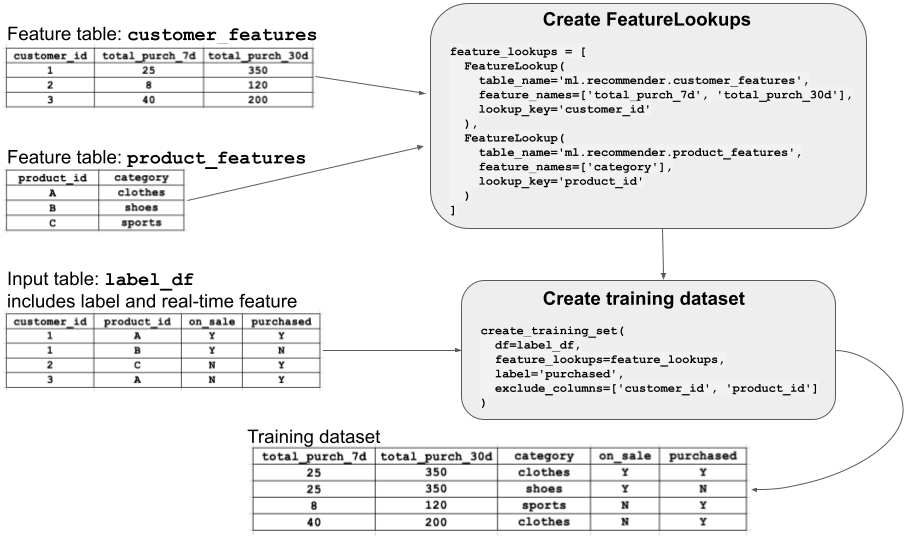
Many different models might use features from a particular feature table, and not all models will need every feature. To train a model using features, you create a FeatureLookup for each feature table. The FeatureLookup specifies which features to use from the table, and also defines the keys to use to join the feature table to the label data passed to create_training_set.
The diagram illustrates how a FeatureLookup works. In this example, you want to train a model using features from two feature tables, customer_features and product_features. You create a FeatureLookup for each feature table, specifying the name of the table, the features (columns) to select from the table, and the lookup key to use when the joining features to create a training dataset.
You then call create_training_set, also shown in the diagram. This API call specifies the DataFrame that contains the raw training data (label_df), the FeatureLookups to use, and label, a column that contains the ground truth. The training data must contain column(s) corresponding to each of the primary keys of the feature tables. The data in the feature tables is joined to the input DataFrame according to these keys. The result is shown in the diagram as the “Training dataset”.
FeatureFunction
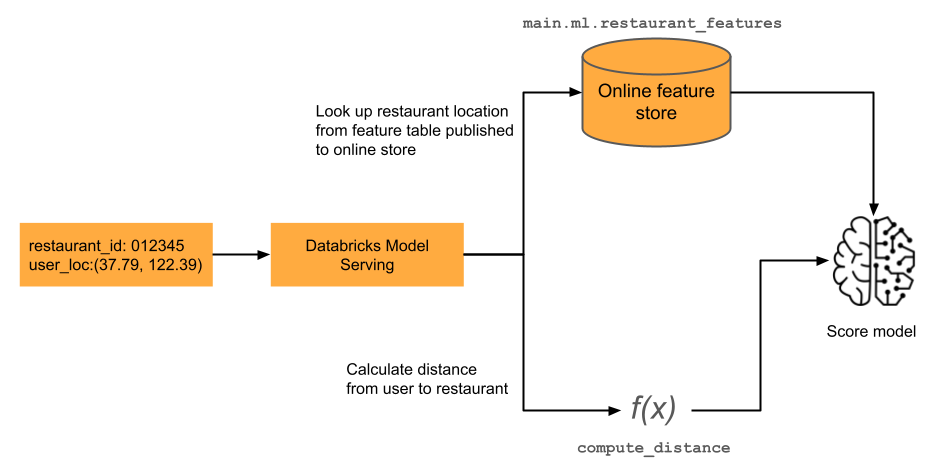
A feature might depend on information that is only available at the time of inference. You can specify a FeatureFunction that combines real-time inputs with feature values to compute up-to-date feature values. An example is shown in the diagram. For details, see On-demand feature computation.
Training set
A training set consists of a list of features and a DataFrame containing raw training data, labels, and primary keys by which to look up features. You create the training set by specifying features to extract from Feature Store, and provide the training set as input during model training.
See Create a training dataset for an example of how to create and use a training set.
When you train and log a model using Feature Engineering in Unity Catalog, you can view the model's lineage in Catalog Explorer. Tables and functions that were used to create the model are automatically tracked and displayed. See Feature governance and lineage.
FeatureSpec
A FeatureSpec is a Unity Catalog entity that defines a reusable set of features and functions for serving. FeatureSpecs combine FeatureLookups from feature tables and FeatureFunctions into a single logical unit that can be used in model training or served using Feature Serving endpoints.
FeatureSpecs are stored and managed by Unity Catalog, with full lineage tracking to their constituent offline feature tables and functions. This enables governance, discoverability, and reuse across different models and applications.
You can use a FeatureSpec in the following ways:
- Create a Feature Serving endpoint using the Python API or REST API. See Serve feature tables or deploy directly using the Model Serving UI. For high performance applications, enable route optimization.
- Use in model training by referencing the
FeatureSpecincreate_training_set.
A FeatureSpec always references the offline feature tables, but they must be published to an online store for real-time serving scenarios.
Time series feature tables (point-in-time lookups)
The data used to train a model often has time dependencies built into it. When you build the model, you must consider only feature values up until the time of the observed target value. If you train on features based on data measured after the timestamp of the target value, the model's performance may suffer.
Time series feature tables include a timestamp column that ensures that each row in the training dataset represents the latest known feature values as of the row's timestamp. You should use time series feature tables whenever feature values change over time, for example with time series data, event-based data, or time-aggregated data.
When you create a time series feature table, you specify time-related columns in your primary keys to be time series columns using the timeseries_columns argument (for Feature Engineering in Unity Catalog) or the timestamp_keys argument (for Workspace Feature Store). This enables point-in-time lookups when you use create_training_set or score_batch. The system performs an as-of timestamp join, using the timestamp_lookup_key you specify.
If you do not use the timeseries_columns argument or the timestamp_keys argument, and only designate a time series column as a primary key column, Feature Store does not apply point-in-time logic to the time series column during joins. Instead, it matches only rows with an exact time match instead of matching all rows prior to the timestamp.
Offline store
The offline feature store is used for feature discovery, model training, and batch inference. It contains feature tables materialized as Delta tables.
Online feature store
The Databricks Online Feature Store is a high-performance, scalable solution for serving feature data to online applications and real-time machine learning models.
Powered by Databricks Lakebase, it provides low-latency access to feature data at a high scale while maintaining governance, lineage, and consistency with your feature data.
You can provision Online Stores in the serverless Lakebase platform. APIs allow you to manage instances and read-replicas and scale instances as needed. You can use convenient APIs to publish Unity Catalog tables into online stores. These tables are also Unity Catalog entities that natively track lineage to the source tables.
Databricks also supports third-party online stores.
Streaming
In addition to batch writes, Databricks Feature Store supports streaming. You can write feature values to a feature table from a streaming source, and feature computation code can utilize Structured Streaming to transform raw data streams into features.
You can also stream feature tables from the offline store to an online store.
Model packaging
When you train a machine learning model using Feature Engineering in Unity Catalog or Workspace Feature Store and log it using the client's log_model() method, the model retains references to these features. At inference time, the model can optionally retrieve feature values automatically. The caller only needs to provide the primary key of the features used in the model (for example, user_id), and the model retrieves all required feature values.
In batch inference, feature values are retrieved from the offline store and joined with new data prior to scoring. In real-time inference, feature values are retrieved from the online store.
To package a model with feature metadata, use FeatureEngineeringClient.log_model (for Feature Engineering in Unity Catalog) or FeatureStoreClient.log_model (for Workspace Feature Store).